Shared by @DaniYogatama ↗
 reka.ai1mo ago

 Shared by @skalskip92 ↗
 blog.roboflow.com1mo ago
Generating long-duration, high-definition, and rhythmically synchronized dance videos directly from music remains a significant challenge, primarily due to the temporal constraints of current diffusion models, which typically fail beyond 20 seconds. Exist
 Shared by @ai-firehose.column.social ↗
 arxiv.org1mo ago

We’re on a journey to advance and democratize artificial intelligence through open source and open science.
DeepLabCut™️ is a toolbox for state-of-the-art markerless pose estimation of animals performing various behaviors. As long as you can see (label) what you want to track, you can use this toolbox, as it is animal and object agnostic. Read a short developme


 Product Hunt2mo ago
Personalizing text-to-image diffusion models to render several specific subjects in a coherent image remains challenging: the model must preserve each subject's identity while keeping the scene spatially and visually coherent. Methods that fuse independen
Shared by @ai-firehose.column.social ↗arxiv.org2mo agoBuilding performant Vision-Language Models (VLMs) requires carefully curating large-scale training datasets, yet the community lacks systematic benchmarks for evaluating such curation strategies. We introduce DataComp for VLMs (DCVLM), a benchmark for con
 Shared by @lschmidt3 ↗arxiv.org2mo ago

 Shared by @_akhaliq ↗
 github.com2mo ago

 Shared by @chris_j_paxton ↗
 macrodata.co2mo ago

 krea.ai2mo ago
 Product Hunt2mo ago
 Shared by @plosone.org ↗
 plos.io2mo ago
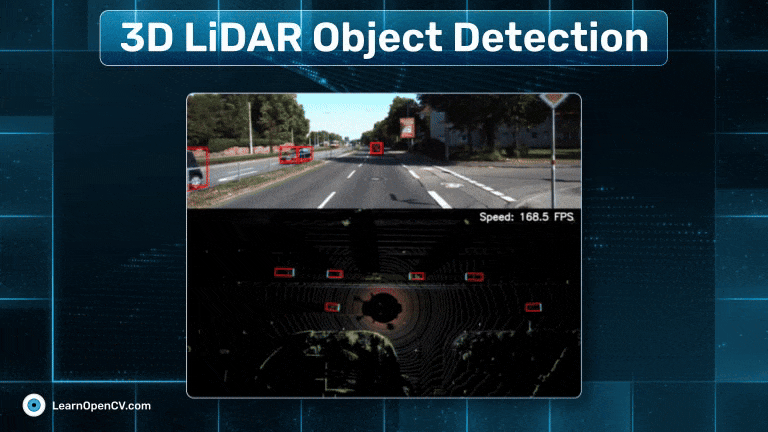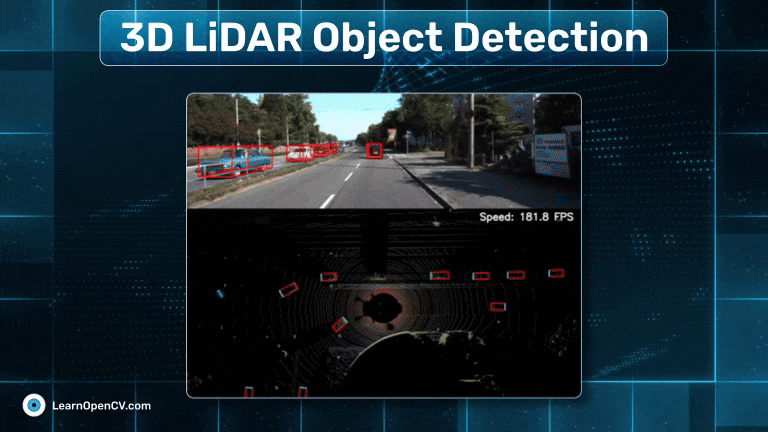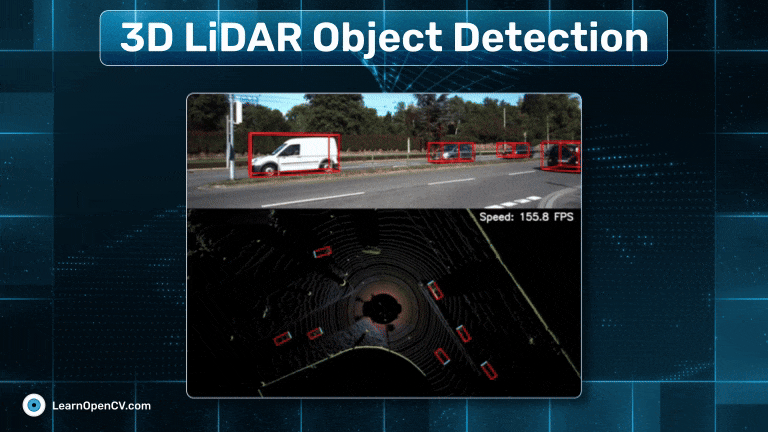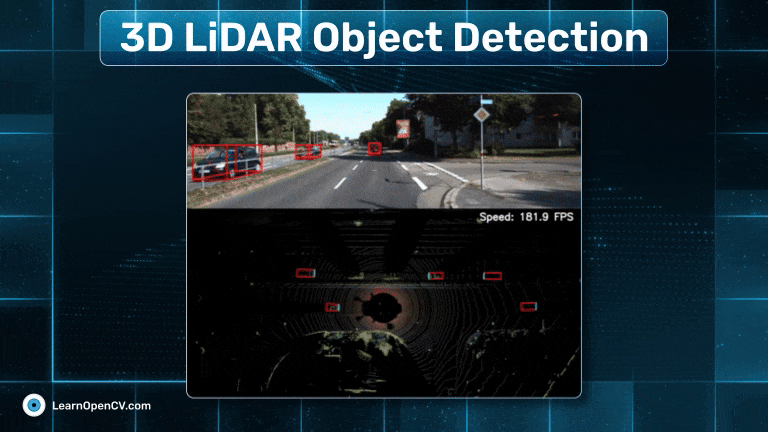
 Shared by @LearnOpenCV ↗
 learnopencv.com2mo ago