
moondream.ai · 15 min
0
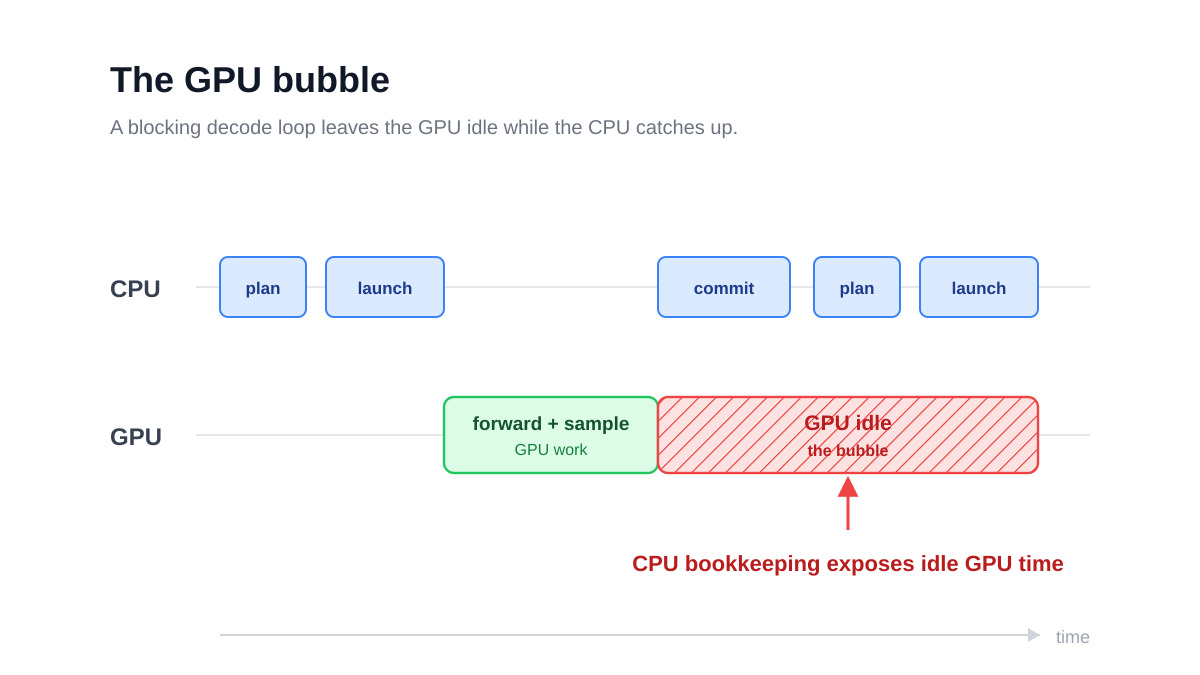
Moondream's deep dive into the 'GPU bubble' shows that during AI inference, GPUs often sit idle waiting on CPU instructions. Their Photon engine achieves ~33ms vision-language inference on B200 by optimizing utilization, with up to 35% higher decode throughput, a concrete look at where inference bottlenecks actually live.