From 187 feeds, newest first.

 vettedconsumer.com3mo ago
 Shared by @PyTorch ↗
 developer.nvidia.com3mo ago

 Shared by @foobar.eagleusb.com ↗
 unsloth.ai4mo ago
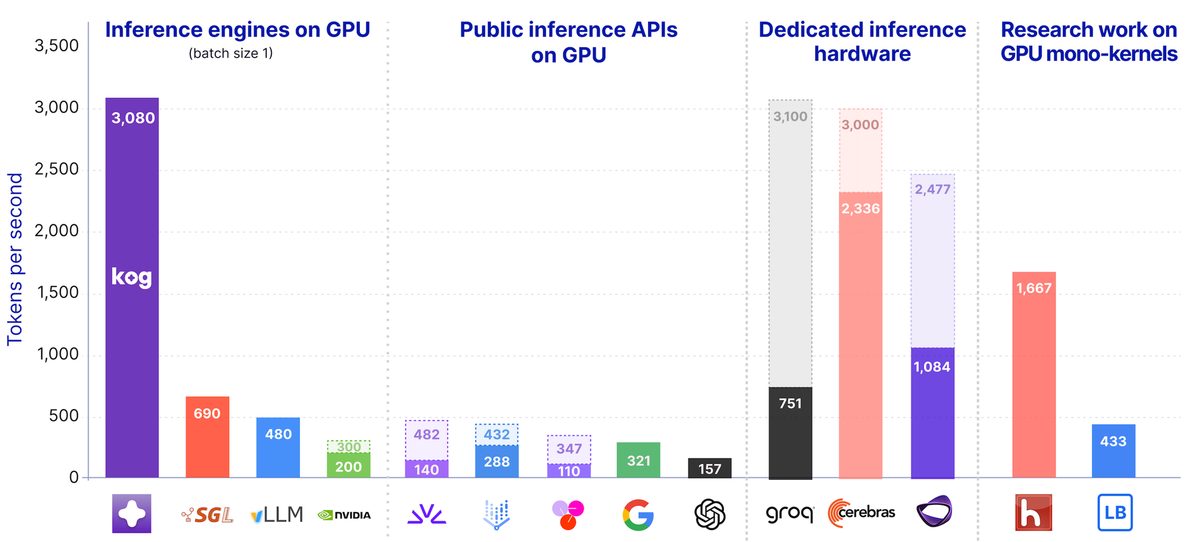
Today, Kog AI launches a tech preview of the Kog Inference Engine (KIE): 3,000 output tokens/s per request on 8× AMD MI300X GPUs and 2,100 on 8× NVIDIA H200 (FP16, no speculative decoding). This preview runs a 2B model, with support for large third-party
 blog.kog.ai·Hacker News: Front Page·5mo ago·18 min read
LLM inference that gets faster as you use it. Our runtime-learning accelerator adapts continuously to your workload, delivering 500 TPS on DeepSeek-V3.1, a 4x speedup over baseline performance without manual tuning.
 together.ai·Hacker News: Front Page·1y ago·10 min read